Robots.txt Guide: Rules, Noindex Differences, and Testing
April 25, 2026
Author: Shusaku Yosa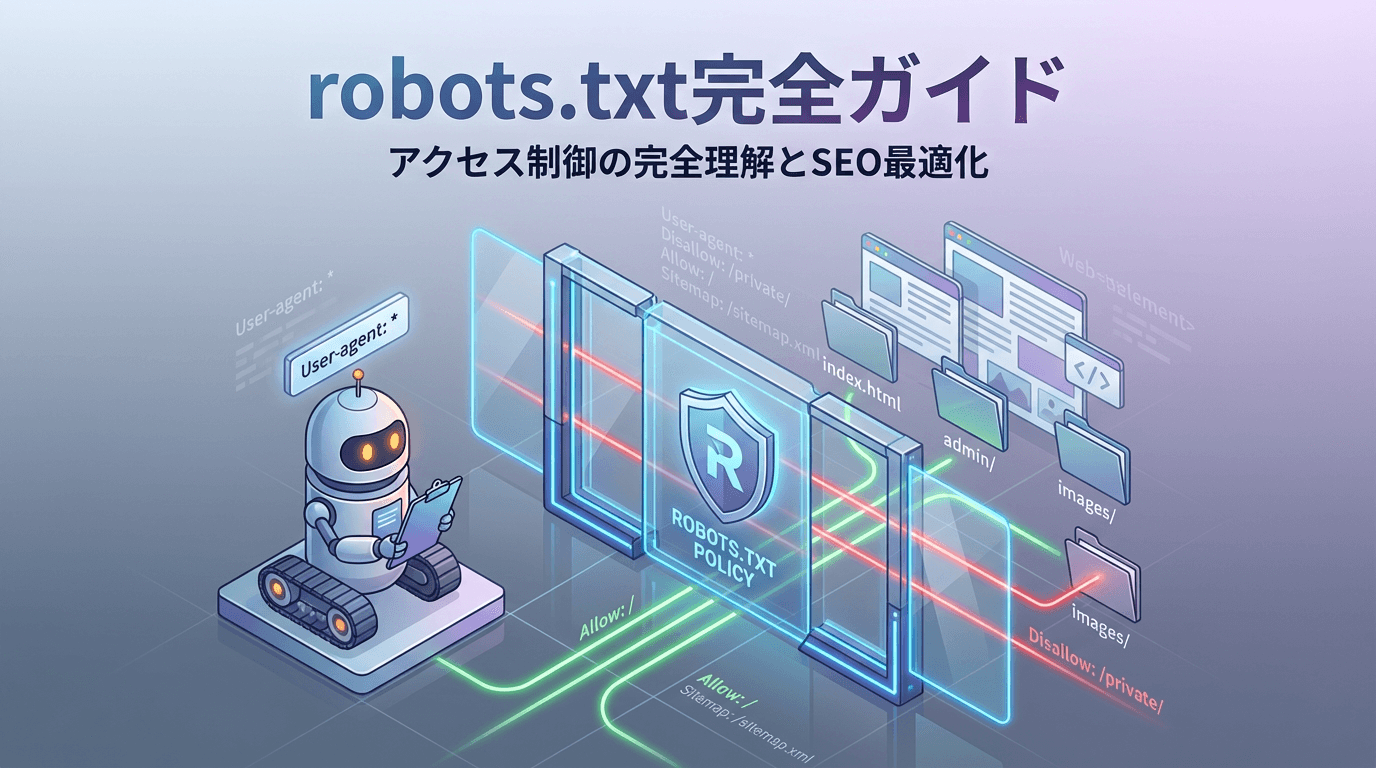
Robots.txt tells cooperating crawlers which paths they may or may not fetch. It is not a reliable way to remove a URL from search, and it is not access control for confidential material. Choose the mechanism according to the outcome you need.
Google’s robots.txt introduction distinguishes crawling from indexing. A blocked URL can still be discovered through links and may appear in search without its content being fetched. Do not promise that a Disallow rule will remove a page within a fixed number of days.
Match the tool to the purpose
Purpose | Mechanism to consider | Important limit |
|---|---|---|
Control fetching of unnecessary paths | Robots.txt | It does not directly prohibit indexing |
Keep a public page out of search | Noindex | The crawler needs access to read the instruction |
Protect private information | Authentication and access control | Robots.txt alone offers no protection |
Identify a preferred duplicate URL | Canonicalization and related signals | This is a different job from crawl control |
Temporarily hide a result urgently | Search Console removals where applicable | A lasting solution may still be necessary |
Blocking a page while asking a crawler to read its noindex instruction can defeat the intended workflow. Plan both the instruction and the crawler’s ability to retrieve it. For private material, protect access at the application or server level rather than relying on voluntary crawler behavior.
Understand the location and syntax
Place the file at the root of the relevant host, such as https://example.com/robots.txt. Check scope separately for other hosts, protocols and ports. A file placed in an arbitrary content directory does not automatically control the whole site.
This illustrative file blocks one path while allowing a more specific help area. It is a teaching example, not a configuration to paste into a live site without review.
User-agent: *
Disallow: /private/
Allow: /private/help/Sitemap: https://example.com/sitemap.xml
Test path | Intended result under this example |
|---|---|
/products/chair | Not restricted by these rules |
/private/report | Fetching restricted |
/private/help/start | Allowed by the more specific rule |
/Private/report | Different case; not the same matching path |
User-agent selects the crawler group. Disallow and Allow describe path rules, while Sitemap supplies a sitemap location. Implementation details vary among crawlers. Verify the rules against the documentation for the crawler you intend to control, especially when using wildcards or several groups.
Avoid common operational mistakes
A production Disallow: / can prevent broad crawling if copied from a staging environment. Blocking resources required for rendering can also interfere with a search engine’s understanding of the page. Keep representative article, category, image and script URLs in a test set.
Do not assume that listing a confidential path hides it: the robots file is itself public. Nor should you accumulate competing groups without checking which group applies to the intended crawler. A simple, documented change is easier to diagnose than a large collection of inherited exceptions.
Use a change and rollback checklist
Stage | Check | Record |
|---|---|---|
Before editing | Current file, affected paths and intended outcome | Backup, owner and proposed change |
Validation | Representative allowed and blocked URLs | URL, expected result and observed result |
After deployment | File availability, contents and reporting state | Response status and tool observations |
Follow-up | Unexpected crawl or indexing changes | Before-and-after conditions and other releases |
Rollback | Restore the relevant previous rules | Approver, restored version and recheck |
Use current Search Console robots.txt reporting and URL Inspection where appropriate. The former crawl-rate limiter ended on January 8, 2024; it should not be presented as a current control. Reporting and recrawling may take time, so distinguish a saved file from evidence that a crawler has retrieved and applied it.
For a failed change, restore the known version and recheck the same representative paths. Keep the failure and recovery timestamps. Without that record, a later traffic change can be mistakenly attributed to content editing, advertising or another unrelated release.
Treat AI crawler controls as purpose-specific
A provider may operate separate crawlers for search, training and user-triggered retrieval. Check its published agent names, purposes and supported behavior before designing rules. Similar names do not imply that one instruction controls every type of access.
Finally, separate content quality from technical access. When a page is absent from search, investigate response status, crawl restrictions, indexing instructions and canonical selection alongside the page’s usefulness. Robots.txt is one part of that diagnosis, not a universal explanation or a guaranteed indexing remedy.
Related guides
- Content SEO: Search Intent, Article Briefs, and an Update Workflow
- How Long Does SEO Take? Metrics and Review Checkpoints
- Content Marketing vs. SEO: Goals, Tactics, and Shared KPIs
Review your results consistently
For ongoing data aggregation, comparison and reporting, review NeX-Ray’s integrations and features. Check the plan requirements for your analysis, then start for free.
Sources and verification
Public documentation checked on October 1, 2026. Availability and interface details can vary by account and market; check the linked documentation before configuring a campaign.